

See it in action
The run was given the published walk as its starting point and this description, which the report’s judge later compares the clip against:Both policies commanded to walk at 0.3 m/s, rendered from the same start with the same camera. 500 iterations of fine-tuning (about 7 minutes of training on an L4) raised velocity tracking from 0.598 to 0.648 and brought the torso from 4.3° to 3.6° off level, measured the same way for both. Run outside Kite, the fine-tuned policy covers 2.94 m in 10 seconds without falling.
Check a spec first
POST /v1/rl_runs/validate takes the same body as a create. It compiles the spec and rolls three canned policies through it on a CPU: zero action, random actions, and, for robots that have one, a published walk that passes the report’s checks. It reports what each reward term pays each of them, and warns when a reward pays for the wrong thing. It creates nothing and costs nothing.
resolved_params lists every parameter as the run would train with it (all 48; a few are shown here). The rollouts are the scale for everything that follows. A trained walk earns about 7 per step here, standing still 5.7, and flailing 3.4 with a fall every two seconds. When standing still earns most of the tracking reward, validate returns idle_policy_scores_high with a patch: the change to your spec that fixes it.
POST /v1/rl_runs/estimate returns only the estimate. Tokens are reserved when you create the run, and whatever training doesn’t use is refunded.
Create an RL run
This is the request the example sent,walk.json:
202 with one run per seed, all sharing a group_id (abridged; the full object is at the end of this page):
robot and task.objective are required. Everything else has a verified default, and the run object echoes the resolved spec back.
Request body
open_duck_mini_v2, microduck, or unitree_g1. GET /v1/rl_runs/catalog lists each robot with its command band and measured training throughput.objective is velocity (walk, turn, or stand on command), imitation (follow a reference motion, motion), or balance (stand on a scene item, item). commands gives velocity runs the ranges each episode’s command is drawn from; any range you leave out keeps the robot’s verified band. scene.items adds physical items (a sphere, box, or capsule with a size, position, and mass). params overrides any reward or randomization parameter; the catalog lists every one with its default and bounds.{"policy": "4d574ce4c547"}) or one of your runs ({"run": "rlr_…"}). mode is fork (its weights and training schedule, with a fresh optimizer) or continue (also its optimizer; your runs only). checkpoint picks a saved iteration of a run.preset is probe (300 iterations, a first signal in minutes) or standard (the iterations each objective was verified with: 4,000 for velocity). iterations overrides the preset. num_envs sets the parallel worlds (default 2,048). max_tokens stops training, keeping its policy, once the run has used that many tokens.group_id.formats adds torchscript. videos adds a clip per command, up to four. huggingface also uploads the bundle to your connected Hugging Face account.2026-09-28. Defaults to the latest, or to the parent’s for a fork or continue of your own run. A run keeps its engine, so a spec trains the same way until you change the date.hardware_tier, visibility, title, metadata, and webhook_metadata are described in the API reference.
Idempotency
Send anIdempotency-Key to make a retried create safe. A retry with the same key and body returns the same runs, even while the first request is still in flight. The same key with a different body returns 409 idempotency_key_reused.
Track progress
PollGET /v1/rl_runs/:id, GET /v1/operations/:id, or subscribe to rl_run.completed, rl_run.failed, and rl_run.canceled webhooks. A run moves queued → processing → succeeded. Within processing, phase says whether it is starting, training, or packaging. A canceled run that has trained shows canceling while its policy is packaged. The example’s status_message read:
metrics carry the latest iteration, the mean reward per step, the same broken down by reward term, and throughput. GET /v1/rl_runs/:id/metrics returns the whole curve, every 5 iterations:
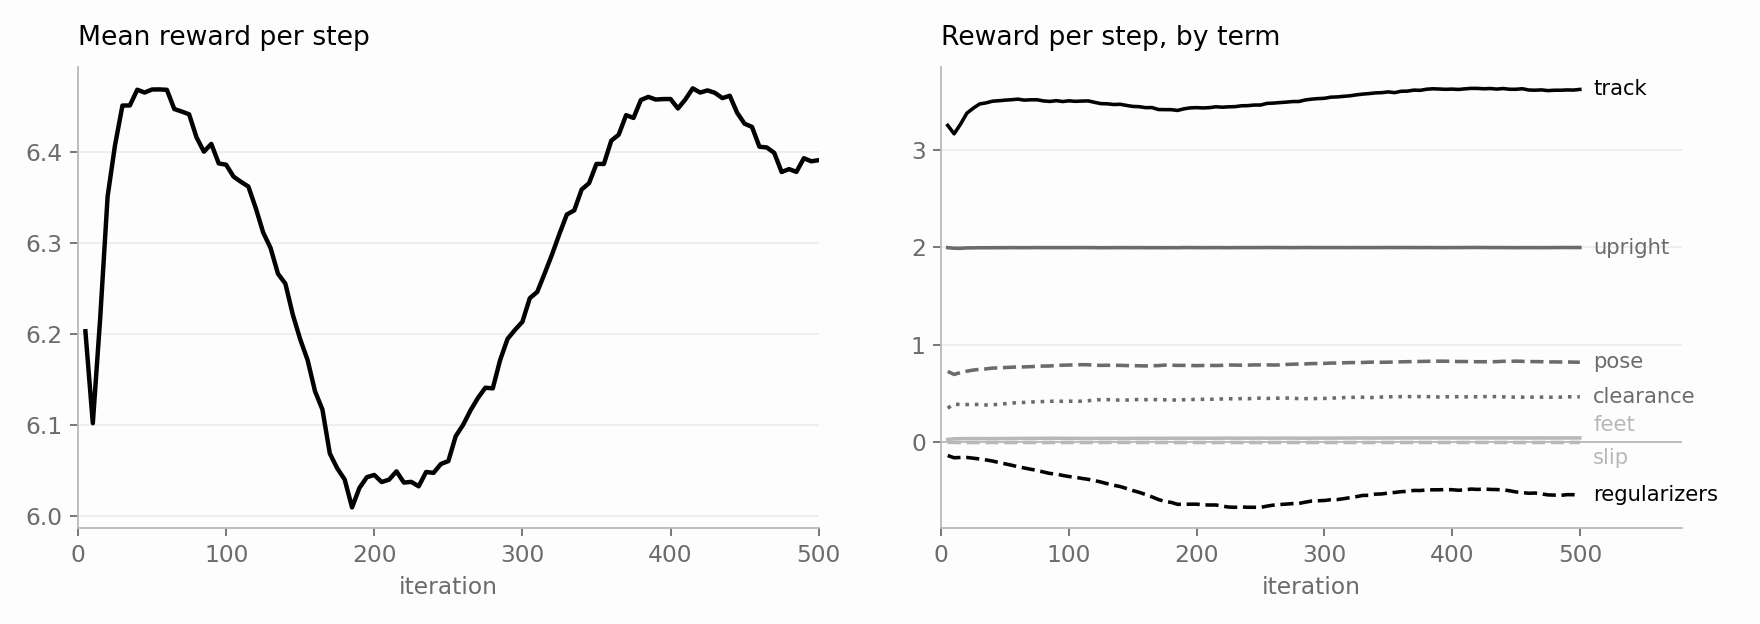
The example's training curve, from GET /v1/rl_runs/:id/metrics. Tracking rises while the regularizers term grows more negative as the smoothness penalties ramp up.
The report
When training ends, Kite compares the last saved checkpoints and keeps the best. It then measures that checkpoint over 24 worlds for 12 seconds each with training noise on, renders it, and exports it.GET /v1/rl_runs/:id/report returns the verdict and how it was reached:
pass when every check passes, and fail otherwise. The judge, a vision model, reads 8 frames of the clean clip against your description:
needs_review when it disagrees with high confidence, but it can never pass a run that failed a check. Its suggestions are reward parameters to scale in a fork. The bundle’s contact sheet shows the same clip:
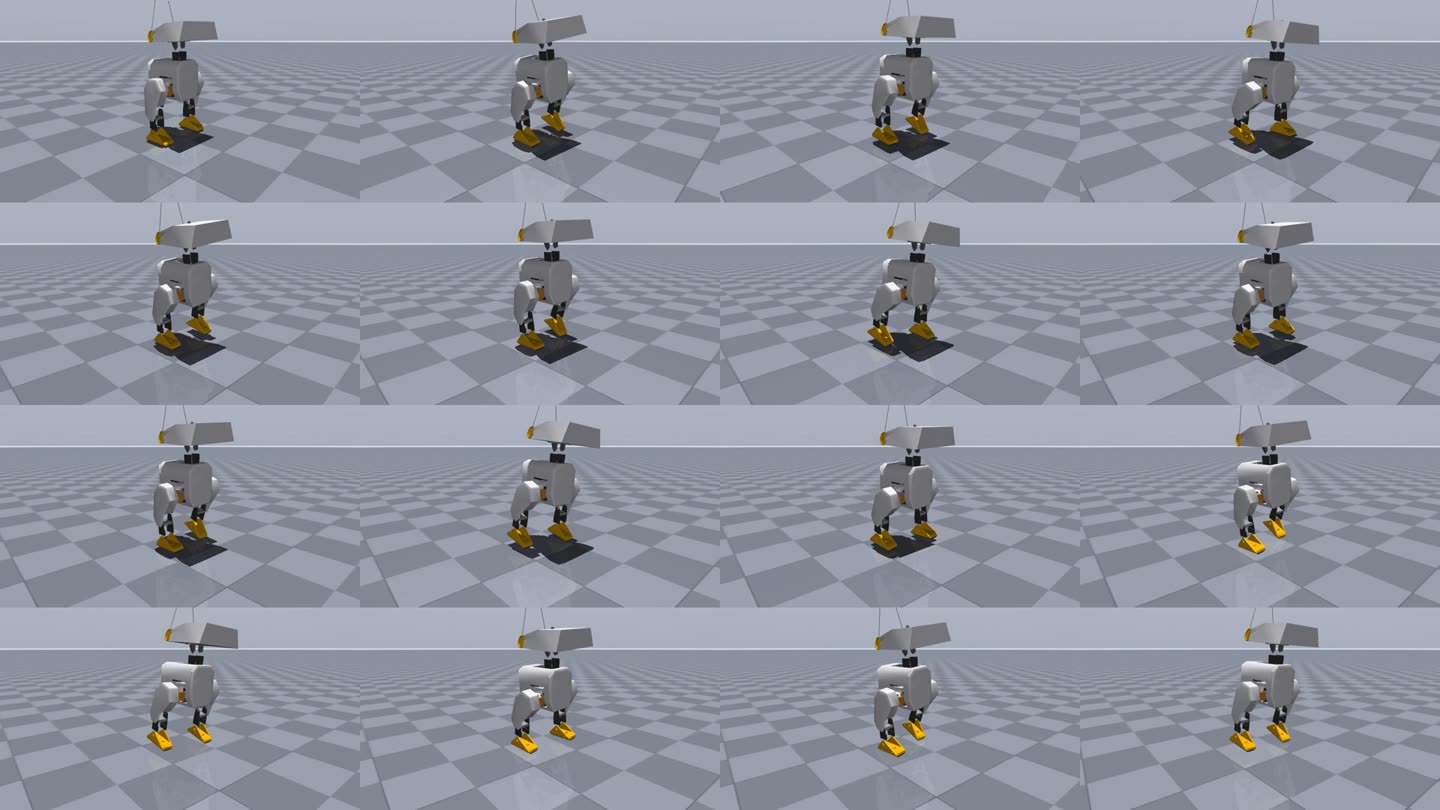
media/sheet.jpg from the example's bundle: 16 frames of the clean clip, the policy walking at 0.3 m/s.
Download the bundle
Once the run is packaged, itsoutput says where everything is. GET /v1/rl_runs/:id/archive returns the bundle as one zip that unpacks to <run id>/; check it against output.sha256. GET /v1/rl_runs/:id/files lists every file with its size and sha256, and GET /v1/rl_runs/:id/files/{path} returns one.
policy/policy.json describes the policy so you can run it anywhere: nine observation blocks (angular velocity, gravity direction, joint positions and velocities, the previous action, the command, foot contact, height, and air time), the action rule (default_pose + scale × action, clipped to the joint limits), PD gains, and the control rate. Any saved checkpoint is also available on its own from GET /v1/rl_runs/:id/checkpoints/:iteration/download, as ONNX by default or with ?format=pt.
Run it
play.py needs only MuJoCo and onnxruntime:
python play.py opens the MuJoCo viewer (on macOS, mjpython play.py), --vx, --vy, and --yaw change the command, and --headless --video out.mp4 records a clip. This is the clip the example asked for in outputs.videos, 8 seconds at 0.3 m/s:
media/cmd_vx0.3.mp4 from the example's bundle.
Iterate
Most runs aren’t right the first time, so the API is built for short loops:- Probe first.
"budget": {"preset": "probe"}trains 300 iterations: enough to see whether the reward teaches the right thing, in minutes. Scale up the spec that works. - Fork what almost works.
"from": {"run": "rlr_…"}starts from a run’s weights and training schedule with this spec, so changing one reward parameter doesn’t mean training from scratch. The judge’ssuggestionsare a good first change."mode": "continue"also keeps its optimizer, to simply train longer. - Run seeds side by side.
"seeds": 3starts three runs of one spec in one group. RL results vary by seed, and the SDK’sbest()picks the winner. - Cap the spend.
budget.max_tokensstops a run at that many tokens and keeps what it learned.
Left, a probe trained from scratch; right, the example’s fork of the published walk. The probe already walks: tracking 0.569, no falls in 10 seconds. It passes every check, but leans 10.4° forward, and its judge noted the lean and mushy foot phasing. The fork starts from a walk that is already good and refines it.
Without writing HTTP
The Kite CLI and Python SDK wrap the whole flow: validate, train, wait, download, and verify.kite rl fork rlr_… --set air_time=4.2 forks a run with one parameter changed; that is the judge’s ×1.4 on the default of 3.0. Agents get the same flow from the MCP tools kite_rl_validate, kite_rl_train, and kite_rl_status, whose next field is the exact download command once the run is packaged.
Cancel
POST /v1/rl_runs/:id/cancel stops a run. A run that has started training keeps the policy it has so far: it reads canceling while that policy is packaged, then canceled, with its outputs, and is charged for the minutes it trained. A run that never started, or left nothing to package, is refunded in full.
Billing
Training is billed by the minute at the tier’s rate. Ongcp_gpu_l4 that is 1,000 tokens per hour. Tokens are reserved at create (the estimate, or budget.max_tokens if lower) and settled when the run ends. The example reserved 167 tokens and was charged 117, for 7 minutes of training; 50 came back. You’re charged only for a run that produces a policy. A failed run, and time spent waiting for a machine, cost nothing. Usage appears under rl_runs in GET /v1/usage.
Errors
A spec is refused before anything is reserved, with a code and the field to fix inparam:
400 parameter_invalid: an unknown robot, a command range outside the robot’s limits, or a scene item out of bounds.400 unknown_paramorparam_out_of_range: atask.paramskey the objective doesn’t have, or a value outside its bounds. The catalog lists both.400 parameter_required: for example, an imitation run withouttask.motion.402 insufficient_tokens:detailshastokens_requiredandcurrent_balance.429 concurrency_limit_exceeded: too many runs in progress. Wait for one to finish, or cancel it.409 run_not_ready: the report, files, or archive of a run that isn’t packaged yet.
error with a code: warm_start_failed, training_diverged, gpu_capacity_unavailable, training_failed, or packaging_failed. Nothing is charged for any of them.